AI visibility
Your next customer may never see a list of search results
They ask an AI assistant, and the assistant answers with one or two names. AI visibility is whether yours can be one of them — and it can be checked, measured and improved.
Three fixed prompts against one live model, in about a minute. No account.
Watch
What gives AI enough evidence to name a business.
One fictional clinic, the answer it was left out of, the five things that have to be true before a business is named, the work on the public evidence, and the re-run. It shows the evidence environment that can be observed and improved, not the inside of any model; nothing in it is a recorded model answer, and every card says so.
Found, understood, corroborated, trusted, named: the model every HighRegard product works to. Follow one question through it, or read what each stage means.
Transcript
A customer asks an assistant who to use. The answer is three names. Yours isn’t one of them.
An assistant doesn’t pick the business with the nicest website. It reads what the web says about you, checks whether the sources agree, and repeats what it can trust. We can’t see inside the model. What we can see, and improve, is the public evidence it reads.
Five things have to be true. It can find you. It understands what you are, and where. Other sources corroborate it. There’s enough evidence to trust. Then, and only then, you get named.
Here’s the clinic it skipped. A service page that never says “pregnancy scan”. A profile in the wrong category. A directory with the old number. No structured data. And nothing anyone else has written about it. Each gap is small. Together, the assistant has no reason to be confident.
So we work on the evidence. One clear entity: one name, one category, everywhere. Services and locations spelled out. Structured data that says what the page says. Profiles, registers and directories made consistent. A page worth citing, written to answer the question. Credentials a machine can verify.
Then we ask again. Same questions, same assistants, weeks later. Some answers now include you. Some still don’t. The sources have changed. What remains becomes next month’s work.
We can’t tell an AI who to recommend. We can improve the evidence it uses to decide.
One question, answered
Follow one customer’s question through the assistant
Five steps, at your own pace: the question, what the assistant reads, what it compares, what the work changes, and the re-test. One fictional clinic throughout.
The question
A customer does not search a list. They ask, and the answer is two or three names with a sentence each. The business that is not in that sentence is not argued with; it is simply absent.
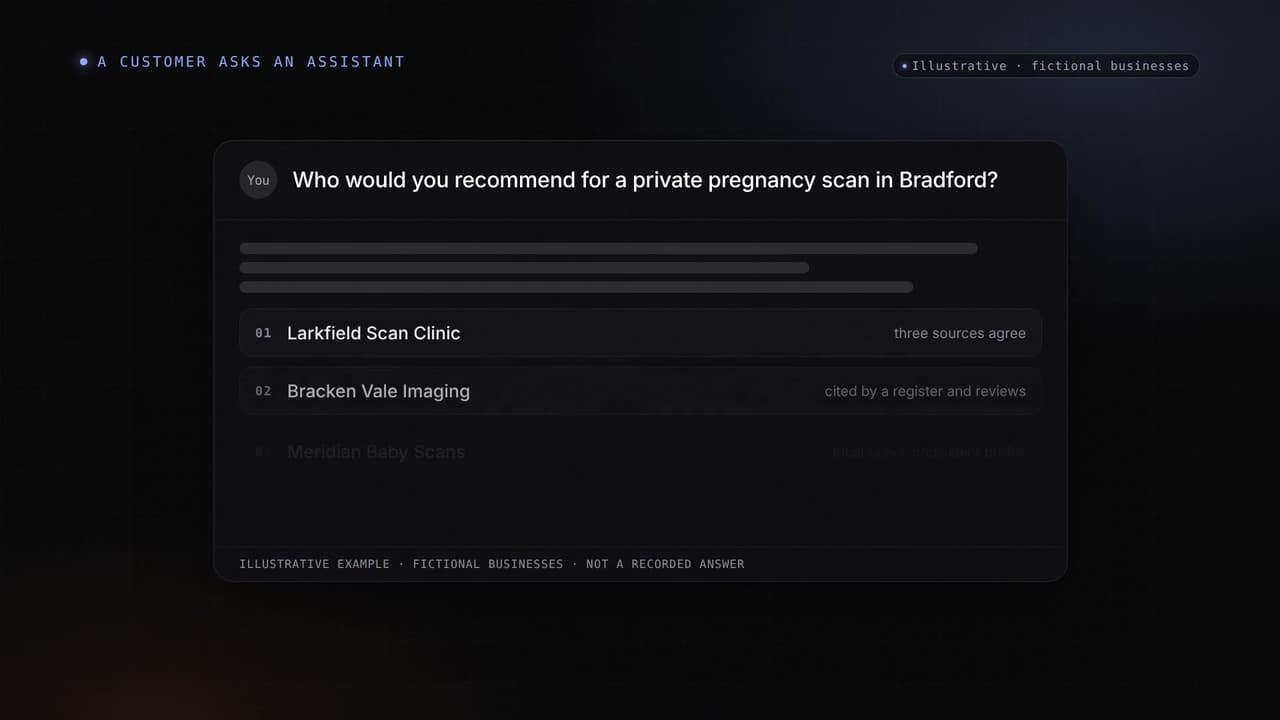
CustomerWho would you recommend for a private pregnancy scan in Bradford?
- Larkfield Scan Clinic consultant-led, early and growth scans, same-week appointments
- Bracken Vale Imaging sonographer-led, clear pricing, evening slots
- Meridian Baby Scans 4D packages, central Bradford
Demo Clinic not named. Nothing said against it. Nothing said at all.
Illustrative: four fictional businesses and a written answer, not a recorded model response.
What it reads
An assistant does not see inside a business. It reads what the public web says about it: the website, the Google Business Profile, directories and registers, reviews, and other pages that mention it. Then it checks whether those sources agree.
Demo Clinic
- Your website
- Business profile
- Directories
- Registers
- Reviews
- Third-party mentions
- Structured data
- Search results
What can be observed and improved is this public evidence, not the model.
What it compares
Across those sources it is looking for the same answers to the same questions. What is this business? Where is it? What does it do, for whom? Do other sources say the same? Is there enough to repeat safely? Thin or inconsistent evidence is where a business drops out.
| Question | Demo Clinic | Bracken Vale Imaging |
|---|---|---|
| What is it? | “Caring for you and your family” | Private ultrasound clinic |
| Where? | No town on the page | Bradford, BD1, on every page |
| Category on its profile | Beauty salon | Medical diagnostic imaging |
| Services, in words | “Scans” | Early, dating, growth, 4D, with prices |
| Do other sources agree? | Two directories, two different names | Register, directories and reviews match |
| Anything worth citing? | Nothing | A pricing page and an FAQ |
What the work changes
None of this is a trick. The work is to remove every reason an assistant has to skip you: say plainly what you do and where, make the profile and the directories agree, add structured data that matches the page, make the trust evidence verifiable, and publish pages worth citing.
- UnderstoodService and location in words, on the page: “Private pregnancy scans in Bradford”.
- UnderstoodStructured data that says exactly what the page says, nothing more.
- CorroboratedOne name, one category, one address on the profile, the directories and the register.
- TrustedCredentials a machine can verify; reviews that describe real services.
- TrustedA page worth citing: prices, what to expect, who performs the scan.
The re-test
The same fixed questions are asked again, on a schedule, and the answers recorded: named or not, who was named instead, the sources cited. Some answers now include you; some still do not. What remains becomes next month’s work. A single answer is a sample; a trend is evidence.
| Prompt | Baseline | Re-test |
|---|---|---|
| Best private scan clinic in Bradford? | Not named | Named, one source cited |
| Who would you recommend for a private pregnancy scan in Bradford? | Not named | Named |
| Is Demo Clinic in Bradford reputable? | “I can’t find much” | Described, not yet recommended |
| Illustrative outcome for a fictional clinic. The real Live Test records the answer, the sources and the date; it does not promise this pattern. | ||
Four fictional businesses, one written question. The point is the mechanism, which can be observed and improved; the answers are illustrations, not recorded model responses, and no outcome is promised.
The model
Five things have to be true before an assistant names you
AI visibility is not a trick. It is the consequence of a business that machines can find, understand, corroborate and trust, then a test of whether that changed what real assistants say.
Found
Can it reach and read you?
Crawlable pages, an indexable site, a presence on the surfaces assistants search.
For an illustrative clinicA clinic’s pages can be crawled; its name appears on the surfaces assistants search.
Understood
What are you, where, for whom?
Explicit service and location language, one business entity, structured data that says what the page says.
For an illustrative clinicThe pages say “private ultrasound clinic in Bradford” in words and in structured data, and both agree.
Corroborated
Does anyone else say the same?
The same name, category and services on your profile, directories, registers, reviews and third-party pages.
For an illustrative clinicThe Google Business Profile, the CQC register and two directories carry the same name, category and address.
Trusted
Is the evidence consistent and supportable enough to repeat?
Public evidence that agrees with itself and can be checked: verifiable credentials, reviews that describe real services, authorship, pages worth citing. A stage in our model, not a score any test reads.
For an illustrative clinicThe registration can be checked, the reviews describe scans, the founder’s credentials are public.
Named
When a customer asks, are you in the answer?
The observed outcome: ask assistants the questions customers ask, repeatedly, and record what comes back. The one stage the Live Test measures directly.
For an illustrative clinicAsked “where can I get a private scan in Bradford?”, an assistant names the clinic and cites a source: the outcome the Live Test records, run after run.
HighRegard’s working model of the evidence journey, used to organise the work and the measurement. It is not a description of any assistant’s internal architecture, weighting or confidence score, none of which we can see. The clinic example is illustrative.
What we change
- Entity clarity: one name, one category, one set of facts, everywhere
- Content that says what you do, for whom, where, and why to believe it
- Structured data that matches the page, with sameAs relationships
- Consistent profiles, registers and directories; relevant third-party corroboration
- Trust evidence made verifiable: credentials, authorship, reviews acquired honestly
- Pages worth citing, because they answer a real question with evidence
- Crawl access: nothing useful blocked, hidden behind scripts or duplicated
- Relevant authority: mentions and references from the sources that matter in your sector, earned not bought
What we cannot
- Which business any single answer names
- A ranking, a guaranteed mention, or a guarantee that any page of yours is cited
- The models’ weighting, or any privileged access to it
- The fact that answers vary by model, session, phrasing, location and day
We cannot tell an AI who to recommend. We can improve the evidence it uses to decide.
How we measure it
A dated baseline, then a retest: named rate across a fixed prompt bank · who was named instead · the sources cited in each answer · description accuracy · the same bank re-run on a schedule, with the method and its limits stated in the report. A single answer is a sample. A trend is evidence. Measured results are reported as measured; why a competitor was chosen is our judgement, and labelled as such. “Trusted” is a stage in our model, not a figure any test reads directly; “Named” is the one stage the Live Test observes.
Find out where your business sits on this model.
Three fixed prompts against one live model, named or not, with the sources it cited — in under a minute. Or talk it through with the founder first.
Or go straight to a product: Free website review, Free · Signature Websites, £749 · Website Revenue Audit, £295 · Repair Sprint, £795 · Monthly plans, from £495/mo · Authority Transformation, £7,495
Three real prompts, one live model, the sources cited in each answer. Named or not, the full answer, and up to six cited sources, dated. Illustrative result on a fictional practice; run it on your own business for a measured one. Who was named instead, and why, is what the audit and the Growth plan work out.
See it on your own business
Three real prompts, one honest answer
The free test asks a live model with web search three fixed questions, and records whether you were named, the full answer, and up to six sources cited in it, with the date. One model, one run: a sample, not a rank. No account, about a minute.
Run the live testWhat has actually changed
An assistant does not show your customer ten options. It answers, with one or two names. The shortlist can be made without a results page ever being seen.
How an assistant decides
It reads, it cross-checks, and then it either names you or leaves you out.
Assistants build answers from what they can read about you across the public web, and from whether those sources agree. Google says its AI features are rooted in the same ranking and quality systems as Search; our own testing is that a business whose information is thin, inconsistent or unreadable to machines is usually left out or described wrongly rather than argued with.
Google guidance Google publishes how its AI features draw on the web, linked at the foot of this page. Measured observation The named / not-named pattern is what our live prompt tests record, dated. Professional judgement “Left out rather than argued with” is our reading from doing the work, not a rule Google has published.
AI visibility is not a trick or a hack. It is whether your business is legible: findable, verifiable and safe for a machine to recommend.
Where it fits
AI visibility runs through everything we sell
It is not an add-on with its own invoice. Every product includes it at the depth that product allows.
If you want a diagnosis only
Free Snapshot & £295 Audit
The audit includes a dedicated AI-discoverability section: what the major assistants can currently work out about your business, where your public sources disagree, and what to fix first — evidenced and dated.
About the auditIf you want the faults fixed
£795 Repair Sprint
Where the audit finds machine-legibility faults — missing structured data, inconsistent business information, pages that answer nothing — the Sprint fixes the highest-priority ones as part of its twelve agreed improvements.
About the SprintIf you want it monitored and improved every month
HighRegard Growth — £795/month
AI answers change as models update and the web changes. The Growth plan tracks how assistants describe you month to month, alongside search and Maps, and feeds what it finds into each month’s improvement cycle.
About the monthly plansIf you want the full rebuild
HighRegard Authority Transformation — £7,495
The full version: two of its eight weeks are devoted to authority evidence and machine legibility, with the AI baseline taken in week one and re-tested at the end — the deepest treatment of this we offer.
About the flagshipQuestions
Honest answers about a hyped subject
Is this the same as SEO?
It overlaps but is not the same. Traditional SEO competes for positions on a results page the customer reads themselves. AI visibility is about whether an assistant that answers on the customer’s behalf can find, verify and confidently repeat what your business is. Much of the underlying work — clarity, structure, consistency, evidence — serves both, which is why we treat them as one discipline rather than selling them separately.
Can you guarantee ChatGPT will recommend my business?
No — and you should not trust anyone who says they can. Nobody outside these companies controls what their assistants say. What can honestly be done is to remove every reason an assistant has to skip you or describe you wrongly: make the facts findable, consistent, structured and evidenced. We measure before and after, and we tell you exactly what we did.
Does this matter yet for a local business?
Increasingly, yes. AI answers now sit above traditional results for many Google searches, and assistants like ChatGPT and Copilot are a normal way for people to ask “who should I use for X near me?”. The practical point is asymmetry: checking and fixing your machine-legibility is cheap now, and being absent from those answers while competitors are present is expensive later.
How do you measure something this new honestly?
With a documented, repeatable test: the same set of realistic customer questions put to the major assistants, recorded with dates, answers and the sources they cite. That baseline is taken before any work and repeated after it. We report what changed and what did not — including where an assistant still ignores you — because a measurement you only report when it flatters the work is not a measurement.
Test your own AI legibility, free
Three of our free tools measure the machine-readable layer this page describes — on your actual website, right now.
Find out what AI assistants can see of your business
The free snapshot includes a first look at your machine-legibility — three real findings, no call required.
Rather talk? Twenty minutes with the founder, UK time slots: you leave with a clear view of what to do first, whether or not you buy anything.
Every way to work with HighRegard
- Free website reviewFreethree findings from your site, two working days
- Signature Websites£749a new, tailored website to a written scope, including VAT
- Website Revenue Audit£295the full report in three working days
- Repair Sprint£795audit plus up to twelve fixes done for you
- Monthly plansfrom £495/moLocal or Growth: measured, fixed, retested each month
- Authority Transformation£7,495eight weeks, founder-led, by application